Tangerine Index lists products launched since ChatGPT and people's reactions to them.

oMLX
omlx.ai
Mac LLM server that cuts agent wait times from 90s to 5s
Open source
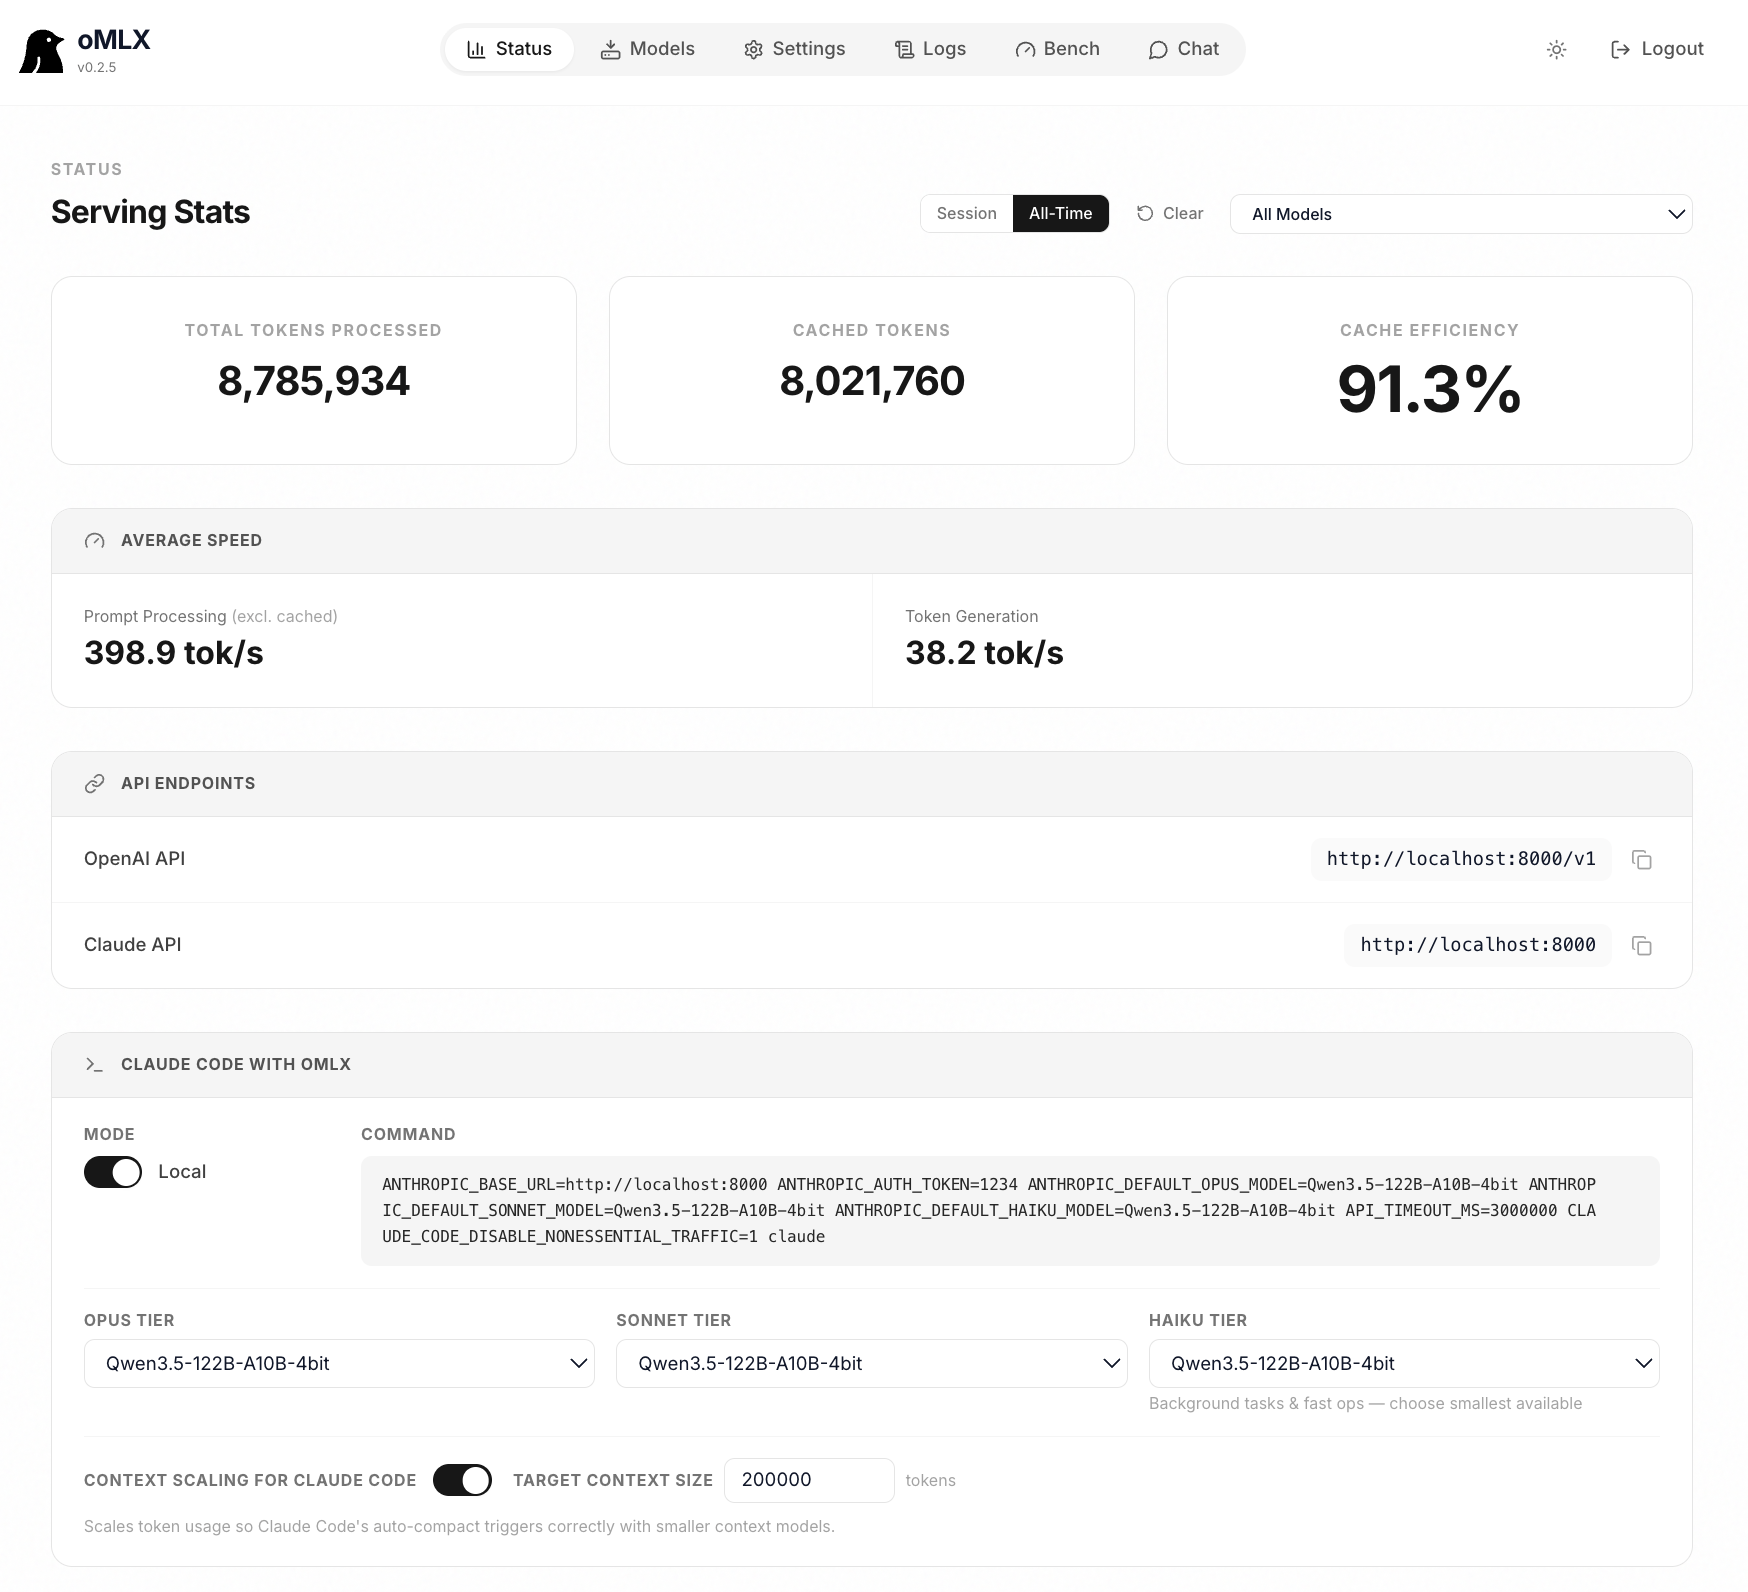
In the makers' words
A native macOS inference server built on MLX. Paged SSD KV caching drops agent TTFT from 30-90s to under 5s. OpenAI & Anthropic compatible API for Apple Silicon. oMLX turns your Mac into a full LLM inference server, run from the menu bar.
Reactions (2)
Similar products
by description similarity
Rapid-MLX
Run local LLMs on Mac, 2-3x faster than alternatives
SwiftLM
⚡ Native MLX Swift LLM inference server for Apple Silicon. OpenAI-compatible API, SSD streaming for 100B+ MoE models, TurboQuant KV cache compression, MACOS + iOS iPhone app.
mlx-serve
Native LLM inference server for Apple Silicon. OpenAI + Anthropic API compatible. No Python. Zig backend, Swift frontend macOS app with chat, music, voice, video generation.
50+ LLMs on 2 GPUs with 2-Second Swapping? We built AI-Native Runtime
InferX: Inference as a Service Platform
Cuts Long Horizon Inference Costs by 50% via external KV Cache Offload
OpenLake is a high performance storage engine for efficient LLM inference and GPU Training

