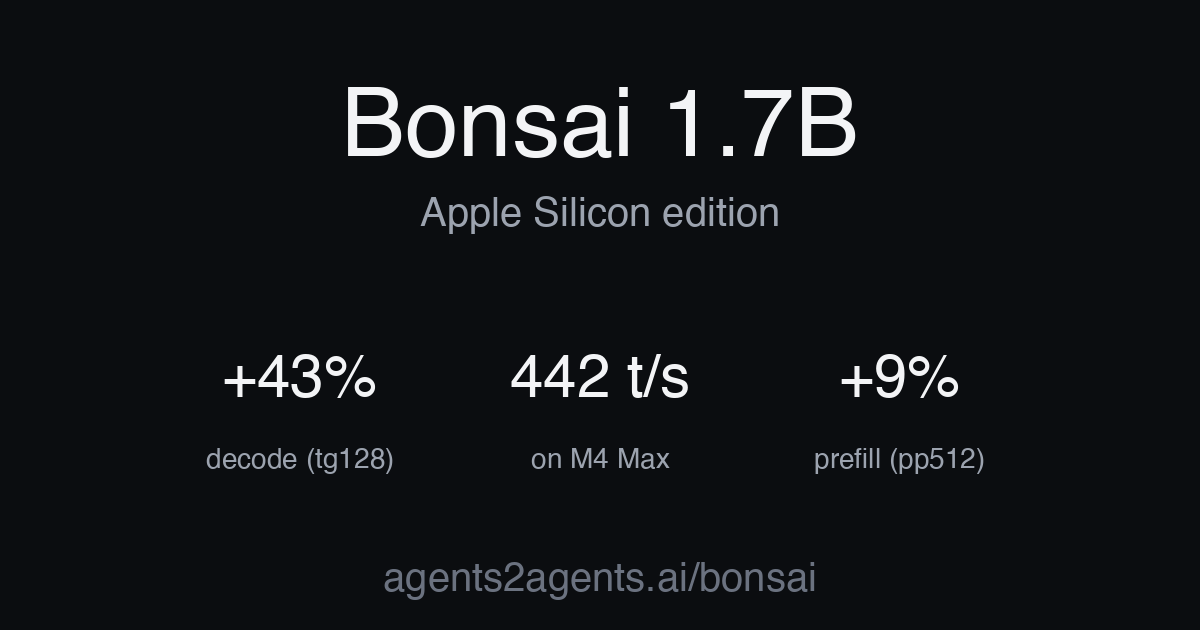
Bonsai 1.7B ternary model at 442T/s on M4 Max
A drop-in optimized inference build of Bonsai 1.7B for Apple Silicon. ~42% faster decode (tg128) and ~9% faster prefill (pp512) on M-series GPUs. All Metal kernels written and tuned by ata, our autonomous engineering agent. We took a recently released Bonsai 1.7B ternary model from PrismML ( https://github.com/PrismML-Eng/Bonsai-demo ) and ran our agentic evolution search on it for 6 hours to optimize the Metal kernels.
반응 (1)
비슷한 프로덕트
설명이 비슷한 순
Running PrismML's Bonsai inside DRAM by breaking DDR4 timing rules
news.ycombinator.comThe excitement surrounding PrismML’s 1-bit/ternary Bonsai models has the industry closely watching how smartphone giants, particularly Apple, will implement LLMs on edge devices.
Bonsai
github.comA Competitive Ternary Weight LLM
OpenGraviton
opengraviton.github.ioRun 500B+ parameter models on a consumer Mac Mini
1-Bit Bonsai
prismml.comthe First Commercially Viable 1-Bit LLMs
A high-performance inference engine for AI models