N0x
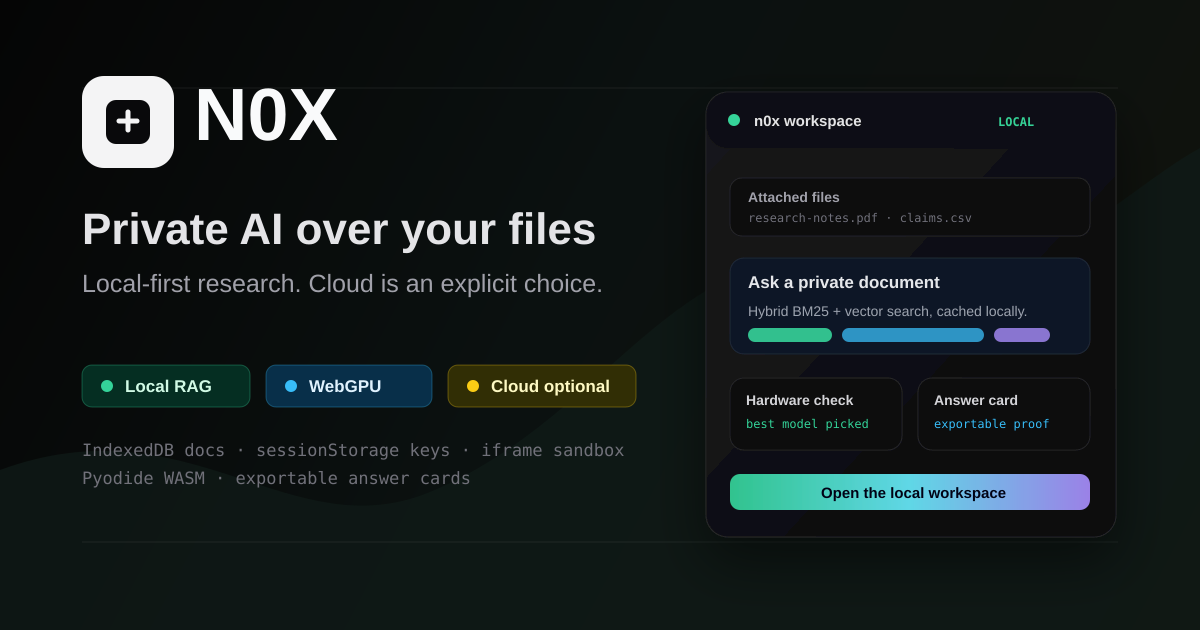
LLM inference, agents, RAG, Python exec in browser, no back end. Ask confidential documents questions in your browser and get filename/chunk citations. Local model, search, and cloud boundaries stay explicit. Built this because I was tired of every AI tool shipping my data to someone else server n0x runs the full stack LLM inference via WebGPU, autonomous ReAct agents, RAG over your own docs, sandboxed Python execution via Pyodide all inside a single browser tab.
반응 (1)
비슷한 프로덕트
설명이 비슷한 순
LLM
github.coma Rust Crate/CLI for CPU Inference of LLMs (LLaMA, GPT-NeoX, etc.)
InferX: Inference as a Service Platform
Run AI models directly in the browser
private-ai-chat.vercel.appno server or internet required
runs 100% locally
Drop in one script tag and your visitors get a private voice and text AI assistant that runs entirely in their browser. No backend, no API keys, no per-message cost. Open source.